Upload MP3, WAV, M4A, AAC, or FLAC recordings. Intexting filters background noise, identifies distinct voices, and delivers finished, export-ready documentation in seconds.
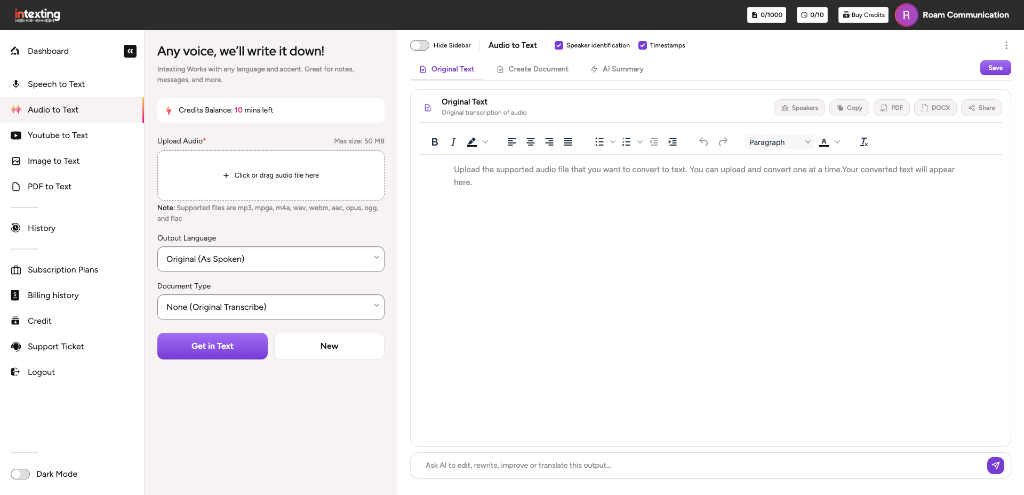
Upload audio, identify speakers, translate outputs, rewrite with AI, and export in every professional format.
Differentiates multiple speakers in the room, assigns dialogue blocks, and lets you rename voices across the entire file with one click.
Transcribe in the original spoken dialect or translate into Marathi (मराठी), Hindi, Tamil, Telugu, English, and 20+ regional Indian and global languages.
Export in print-ready PDF, editable Microsoft Word (.docx), or structured Excel (.xlsx) spreadsheets with Speaker Name, Timecode, and Dialogue columns.
Share a tokenized public URL with clients or team members. External viewers can listen to audio playback and view transcripts without creating an account.
Instruct the built-in AI assistant to polish grammar, condense verbose statements, translate sections, or adjust conversational tone with custom prompts.
Extract core discussion highlights, decisions, and immediate next steps into a structured executive brief with a single click.
Every spoken sentence is synchronized to millisecond timecodes. Toggle timestamps on or off instantly with one switch in the top toolbar.
Convert raw transcripts into structured Minutes of Meeting, Client Notes, Legal Briefs, or School Notes with zero manual copy-pasting.
See how Intexting is purpose-built for offline meetings, in-person discussions, and formal executive documentation compared to generic transcription bots.
| Capability & Feature | Intexting Best Choice | Otter.ai | Notta.ai | Sonix.ai |
|---|---|---|---|---|
| Primary Focus | Offline & In-Person Meetings + Document Synthesis | Virtual Meeting Bots (Zoom/Teams/Meet) | Virtual Bot & Quick Voice Notes | Media & Subtitle File Transcription |
| Executive Documentation | Full MoM, Executive Summary, School Notes, Legal & Field Reports | Generic summary & raw bullet points | Basic action points & brief summary | Raw timestamped transcript only |
| Offline & In-Person Meeting Recording | Direct room recording with voice isolation (No bot intrusion) | Mobile app (primarily built for virtual meeting bots) | Mobile & web mic recording | No live recording (pre-recorded upload only) |
| Multi-Modal Input Sources | Audio, Video, YouTube URLs, Image OCR & PDF | Audio & Video files only (no OCR or YouTube) | Audio, Video & YouTube (no OCR) | Audio & Video files only |
| Speaker Diarization & Custom Names | Multi-speaker detection + Custom label renaming | Yes | Yes | Yes |
| Multi-Language Intelligence | 24+ Languages with Auto-Translation | English only (very limited other languages) | 58 Languages | 38+ Languages |
| Zero-Login Client Sharing | Instant public link (zero signup needed for clients) | Requires recipient account | Requires login for full view | View-only link (restricted on basic plans) |
| Export Options | PDF, Word (DOCX), Excel (XLSX), SRT & Markdown | TXT, PDF, DOCX (restricted on free tier) | TXT, DOCX, PDF, XLSX, SRT | PDF, DOCX, TXT, SRT, VTT |
| Pricing & Value | Free tier · Plans from ₹399/mo (~$4.80) | $16.99 / user / month | $13.99 / user / month | $10.00 / hour or $22/mo |
Why prompting a free conversational AI chatbot cannot replace a dedicated end-to-end meeting recording and executive document synthesis platform.
| Capability & Workflow | Intexting Built for Meetings | ChatGPT (OpenAI) | Google Gemini | Claude (Anthropic) |
|---|---|---|---|---|
| Primary Workflow | Dedicated Offline & In-Person Meeting Documentation | Conversational chatbot & general text assistance | Conversational chatbot & web search integration | Conversational assistant & long-form writing |
| In-Person Audio Recording | Direct mobile/web mic with acoustic echo cancellation | No meeting recorder (voice mode is 1-on-1 chat only) | No meeting recorder (voice input only for search/prompting) | No audio or voice recording feature |
| Continuous Meeting Audio Length | Full 1–3 hour continuous meetings without truncation | Strict 25MB file upload limit (~15-20 min audio) | File limits apply; often hallucinates long spoken audios | Cannot transcribe raw audio files directly |
| Speaker Diarization (Who Said What) | Auto-detects multiple speakers with custom name editing | No speaker separation (treats audio as single speaker blob) | Unreliable speaker attribution; frequent misattribution | N/A (requires external transcript first) |
| Sentence Timestamps & Audio Player Sync | Clickable timestamps synchronized directly with audio waveform | No timestamp sync or interactive audio playback | No interactive audio waveform or timestamp player | No audio player integration |
| Automated Executive Templates | Formal MoM, Executive Summary, Cornell Notes & Legal Reports | Requires manual complex prompt engineering every time | Inconsistent formatting; conversational outputs | Good reasoning but requires manual prompt structuring |
| One-Click Native Export | Formatted PDF, Word (.docx), Excel (.xlsx) & SRT Captions | Copy-paste plain markdown chat text only | Export to Google Docs (raw text unformatted) | Copy-paste plain markdown text only |
| Zero-Login Client Sharing | Instant public link (recipients view without an account) | Shared chat links require ChatGPT login for full view | Public chat sharing requires Google account | Shared artifacts require Claude account |
| Data Privacy & Confidentiality | Confidential meeting encryption; your voice never trains public AI | Free tier conversations train OpenAI models by default | Chats may be reviewed by human annotators by default | Free tier prompts may be used for model training |
Everything you need to know about uploading audio files, speaker separation, timestamps, and exports.
Intexting supports all standard audio formats including MP3, WAV, M4A, AAC, FLAC, OPUS, OGG, and MPGA. Free accounts can upload files up to 10MB, and subscription tiers support files up to 500MB with batch uploads.
Our audio ingestion pipeline includes automated band-pass filtering, dynamic range compression, and speech enhancement algorithms that strip out HVAC hums, boardroom reverberation, and outdoor traffic noise before transcription begins.
Our diarization engine achieves up to 98% accuracy on studio and boardroom recordings. It accurately identifies speaker shifts and provides speaker rename tools so you can replace "Speaker 1" with the real executive name throughout the entire document.
Yes. With Timestamps toggled on, every sentence is time-synchronized. You can export structured spreadsheets (XLSX/CSV) containing columns for Speaker, Timestamp, and Dialogue alongside PDF and Word formats.
Thanks to GPU-accelerated speech models, a 60-minute high-fidelity audio file is typically processed and synthesized in under 90 seconds.
Record conversations on the move, scan whiteboard notes, and generate finished executive Minutes of Meeting in seconds. Seamlessly synced across your phone and web dashboard.